netsi-style-like-expressive-adventure Version 1.0.0
Kaldes med /netsi-style-like-expressive-adventure
Kan du huske, hvordan du som barn studerede en tegneserierude og fandt den lille båd i havnen, det skæve vejskilt og vitsen gemt bag helten? Den slags ruder tegner denne skill. En klar fortællestreg, udtryksfulde figurer og en verden med detaljer helt ned til sidste tovende gør dit foto, din scene eller din idé til et færdigt eventyr. Tricket: stedet er også en hovedperson. Du er stadig dig selv, nu midt på en ekspedition.
Laver et færdigt billede ud fra et foto, en scenebeskrivelse eller en kontekst, der skal illustreres. Forener en klar, levende fortællestreg, figurer med stærkt udtryk, detaljerede og geografisk troværdige omgivelser, dybde fra forgrund til fjerne vartegn, en gag bygget ind i stedet og varme firefarvetryk. Tilbyder valgfrie justeringer af omverden, farver og gag samt et sammenligningsgrid. Dialogen følger dit sprog; de interne billedprompts er engelske.
Ingen Claude Code? Hent SKILL.md og indsæt indholdet som din prompt i en hvilken som helst AI-chat.
Eksempler på prompts
Forslag til at kopiere og prøve. Det er ikke optagne svar.
/netsi-style-like-expressive-adventure Brug stilen på mit vedhæftede foto. Bevar ansigtet, udtrykket, håndens gestik og omgivelserne, så de kan genkendes. Brug standardstilen.
→ Du får en færdig eventyrtegneserie-illustration af dit foto. Skillen undersøger billedet først, bevarer dig genkendelig og gør dine omgivelser til et troværdigt startpunkt for en rejse.
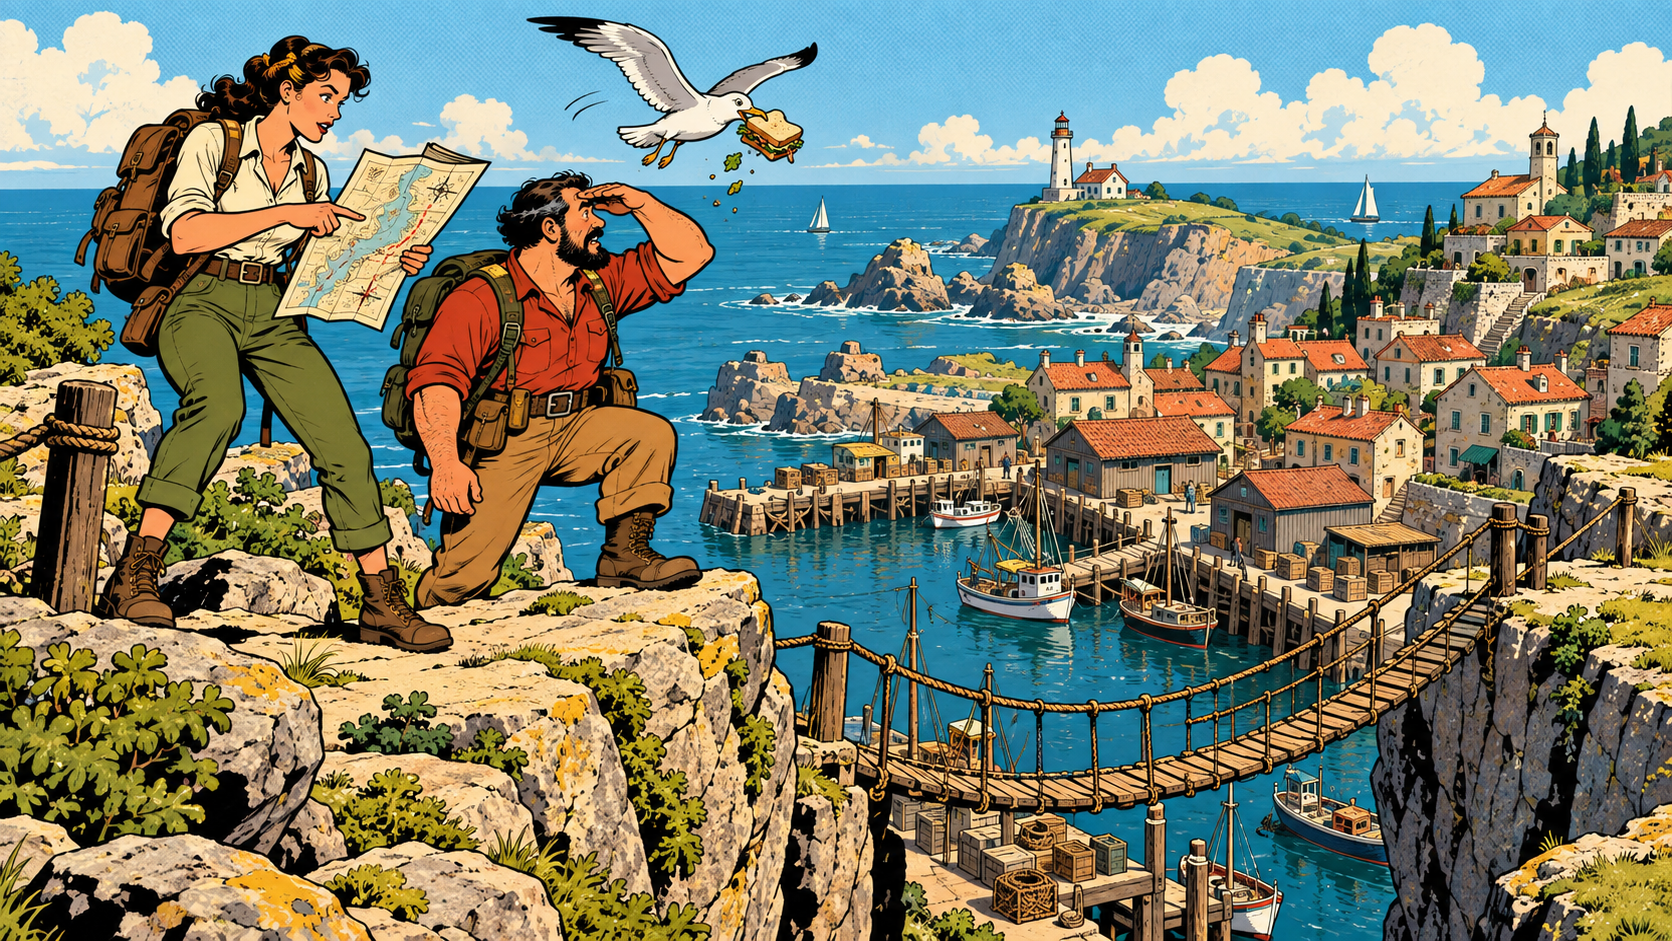
/netsi-style-like-expressive-adventure To opdagelsesrejsende med et håndtegnet kort står på en klippeafsats over en skjult havneby. En hængebro svajer, og en måge stjæler deres madpakke. 16:9, ingen tekst.
→ Du får en færdig scene med klar tuschstreg, dybde fra klippekant til fyrtårn, en havn fuld af konkrete detaljer og flade firefarvetoner. Mågens tyveri udspiller sig midt i landskabet.
/netsi-style-like-expressive-adventure Illustrér den lange vej til en produktlancering til et kickoff-slide. 16:9. Ingen tekst i billedet.
→ Du får en original ekspedition: et lille hold med rygsække og kort ved foden af en snoet bjergsti, med et tændt fyr på den fjerne top. Budskabet kommer frem uden ord eller opdigtede fakta.
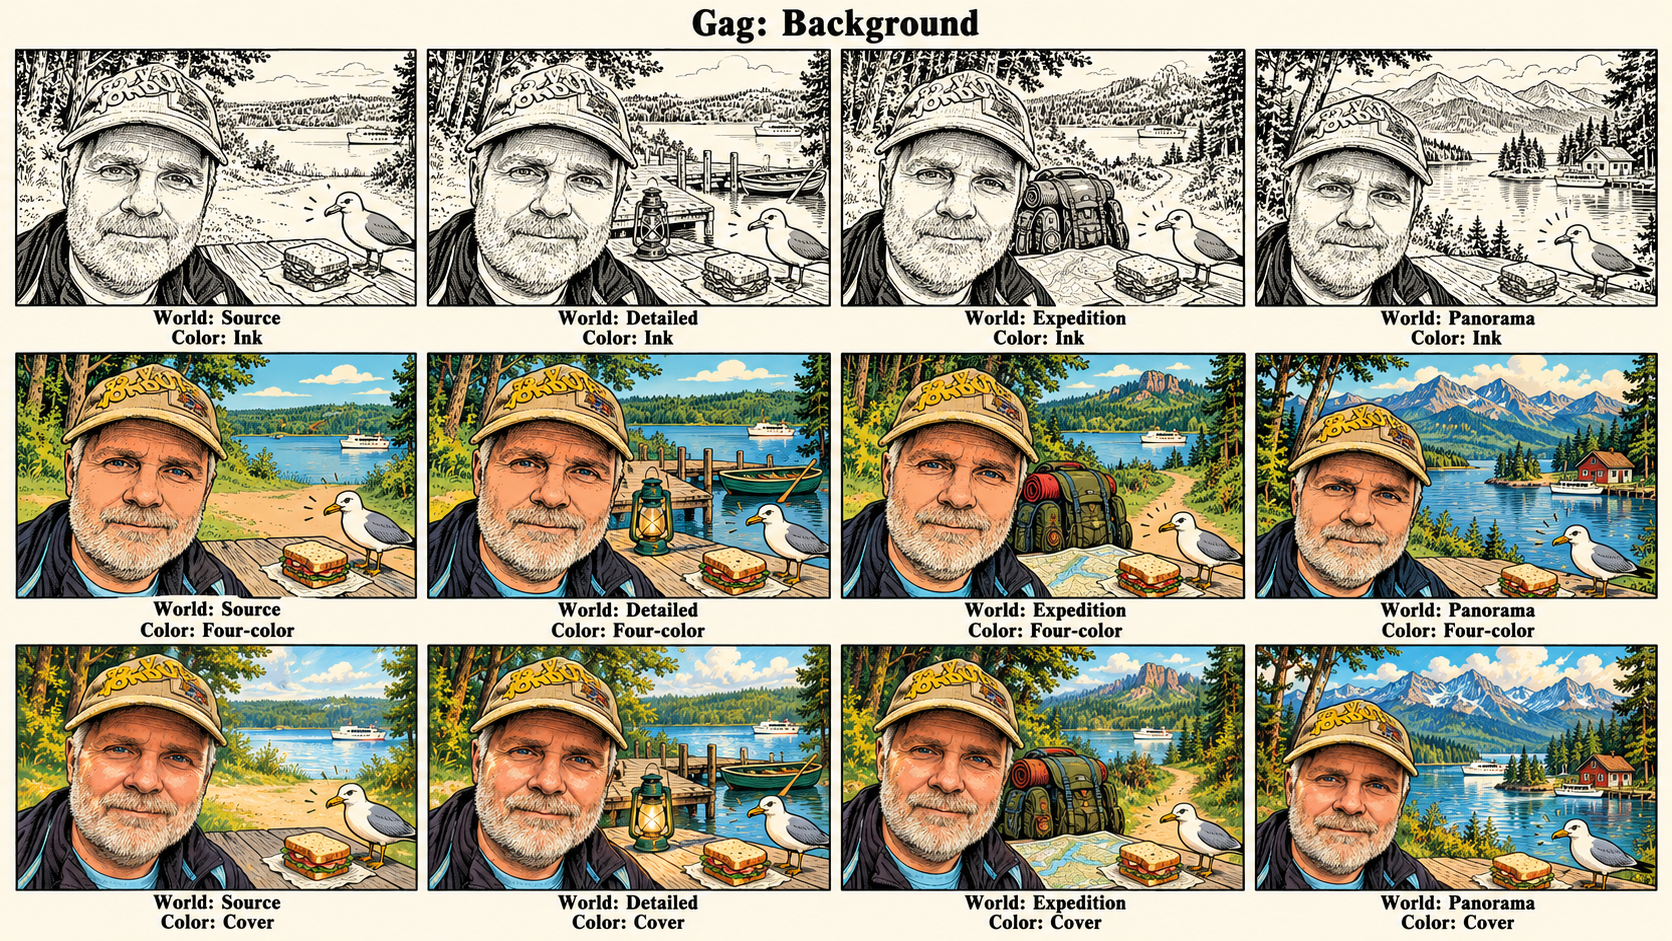
/netsi-style-like-expressive-adventure Brug mit vedhæftede portræt ved søen til at vise World og Color i et grid på 4 × 3. Behold Gag på Background. Ét 16:9-billede med engelske tweak-værdier under hvert felt.
→ Du får 12 sammenlignelige illustrationer i ét billede. Kolonnerne varierer, hvor meget verden omkring dig vokser, rækkerne varierer farverne, og samme person kan genkendes i hvert felt.
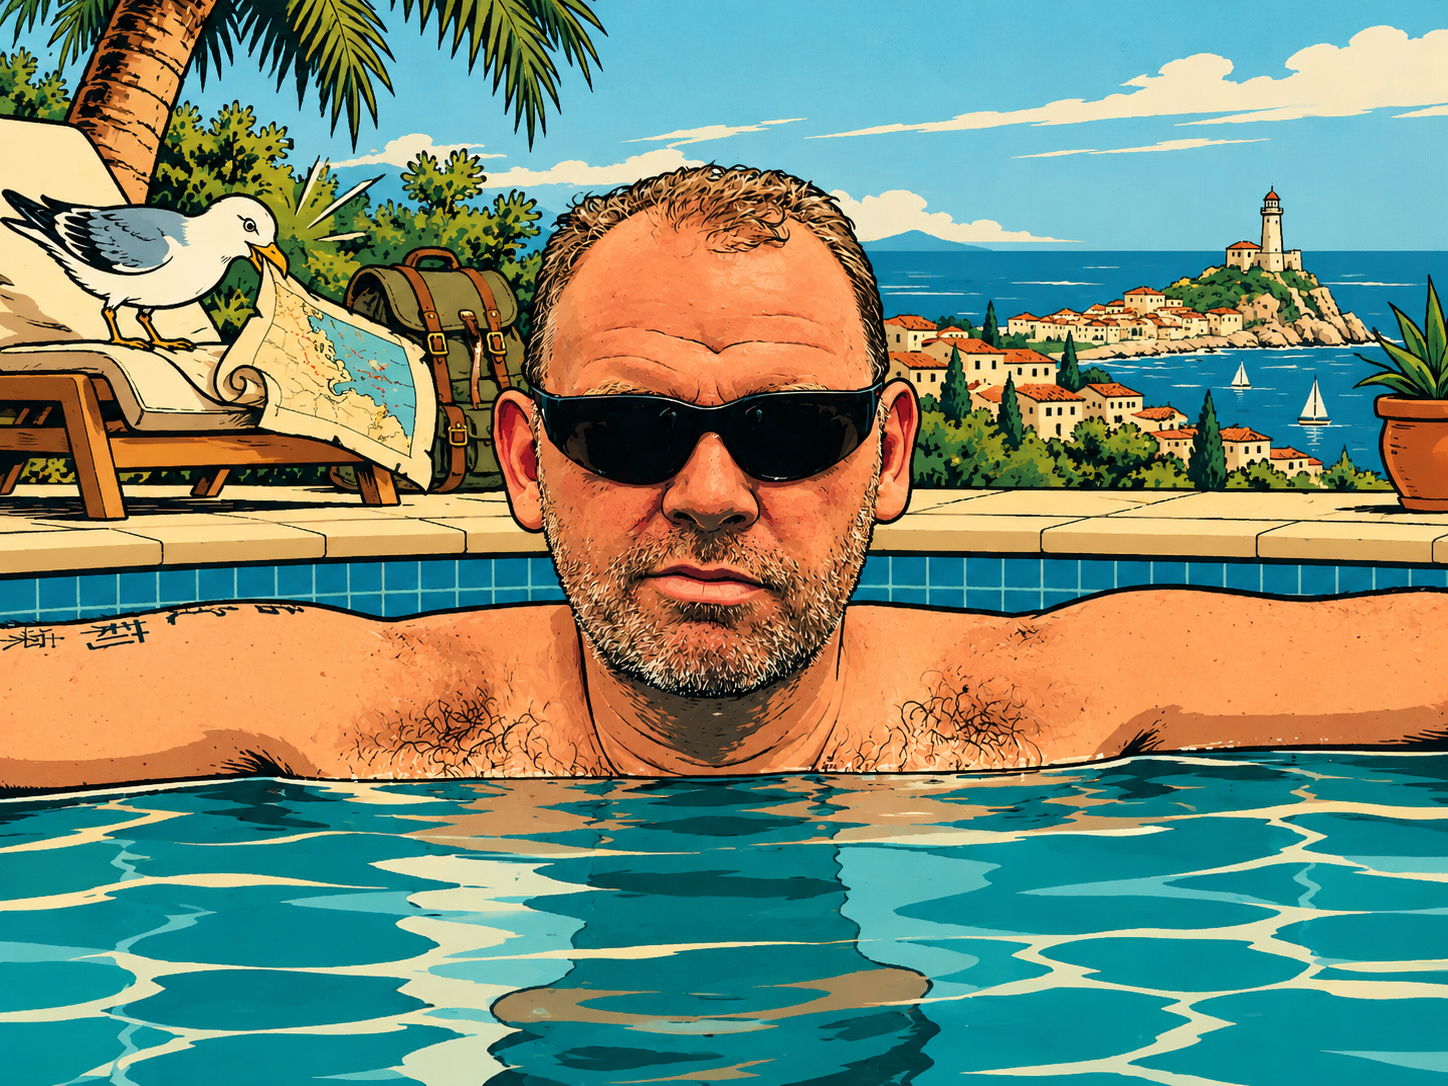
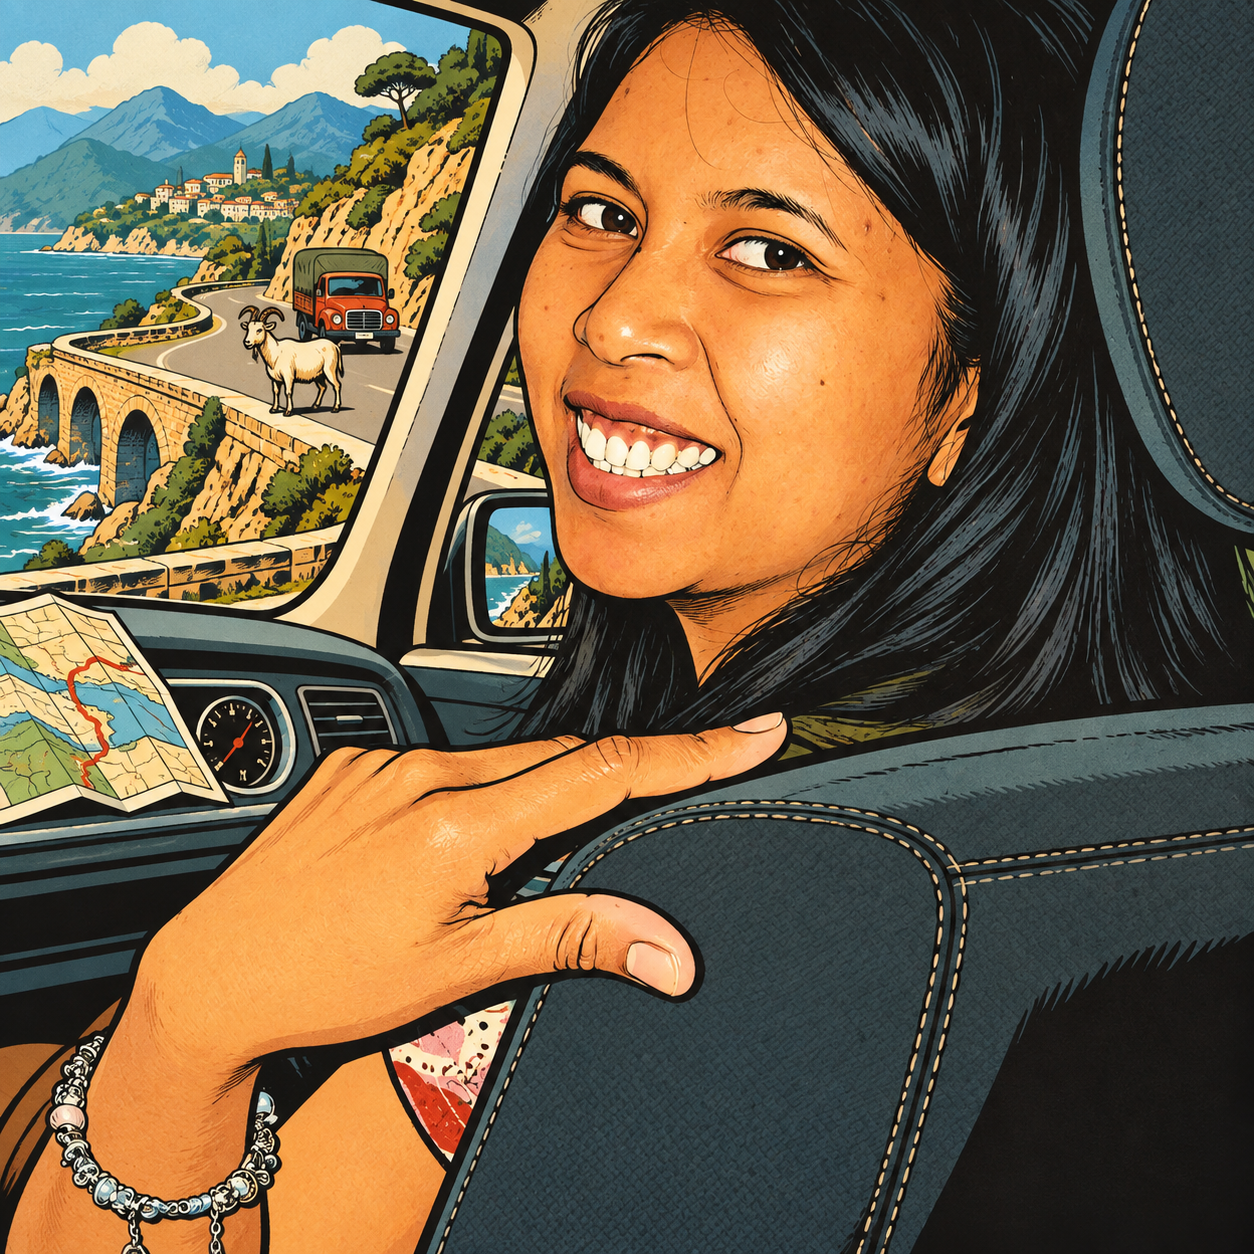
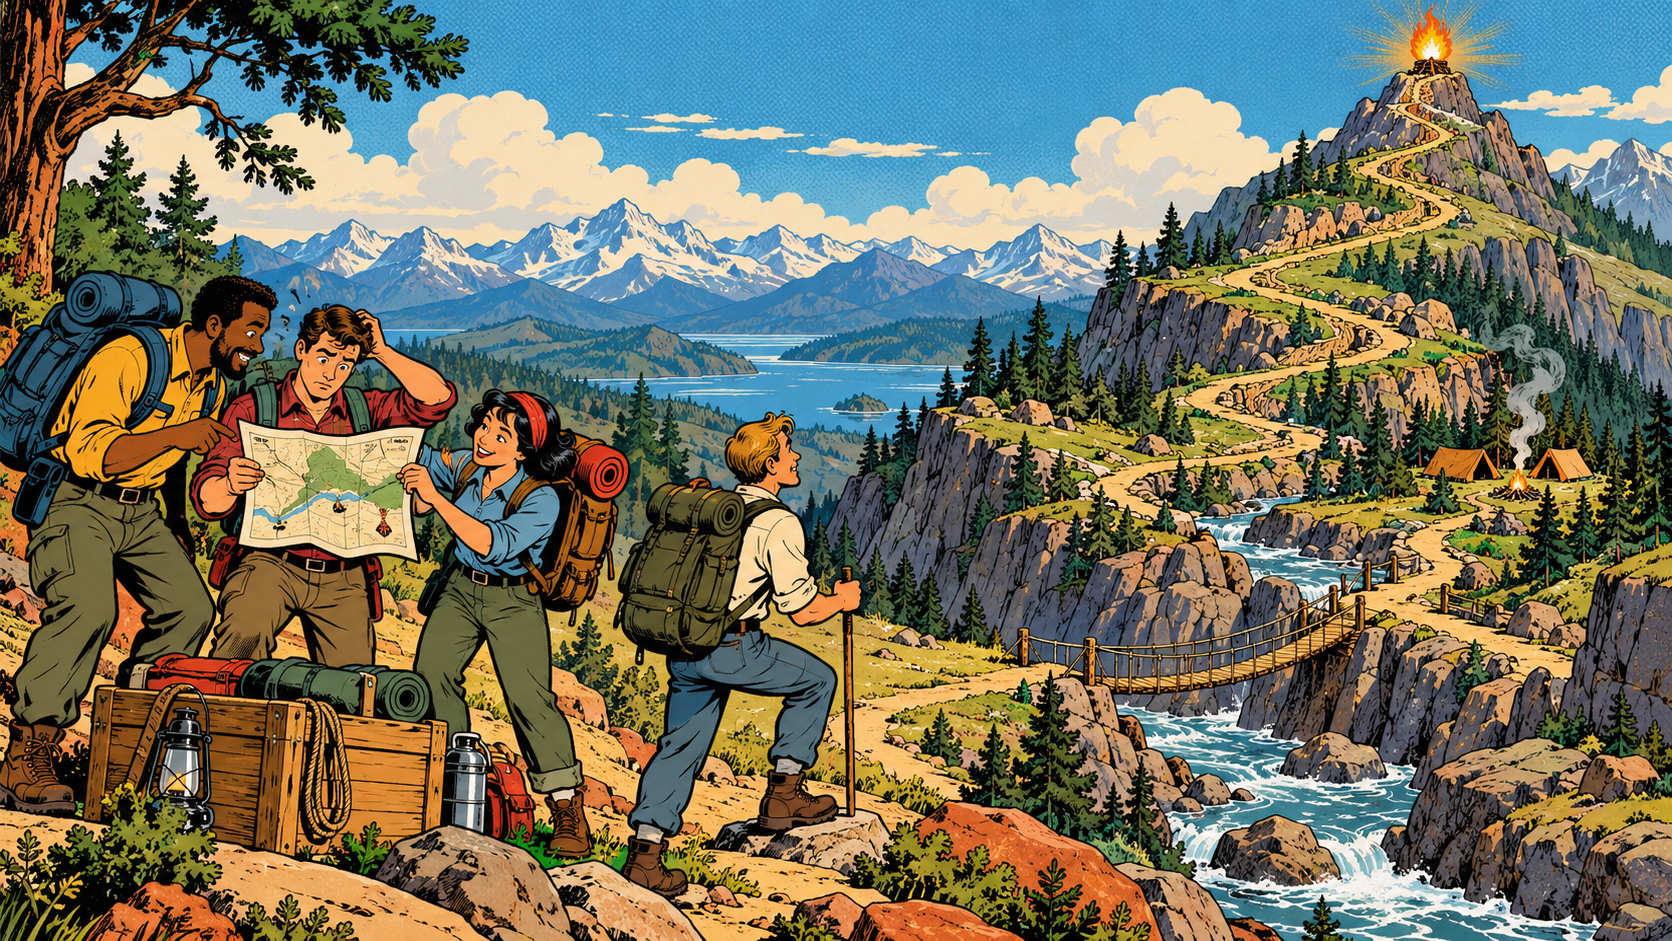
Expressive Adventure
Turn a familiar subject into an expressive adventure-comic illustration. A supplied face stays recognizable; a described scene stays yours; a context becomes a small expedition with a real sense of place and one well-placed gag. The setting is a character too. Deliver the image itself.
Required capabilities and resources
- Use an image-generation/editing tool. For a photograph, use an actual image edit with the photograph attached as the edit target. Do not reconstruct it from a description alone.
- Use netsi-prompt-generator for the internal image prompt. If it is installed, read its instructions. Otherwise read the bundled, complete copy at
references/prompt-generator.mdand apply that skill's workflow to the prompt subtask. - Read
references/style-profile.mdbefore composing the prompt, andreferences/tweaks.mdwhen adjustments or a comparison are relevant. - Inspect the bundled generated examples in
https://assets.netsi.dk/skills/netsi-style-like-expressive-adventure/images/as anonymous visual calibration, especiallyhttps://assets.netsi.dk/skills/netsi-style-like-expressive-adventure/images/04-cliff-harbor.pngfor environment detail and color andhttps://assets.netsi.dk/skills/netsi-style-like-expressive-adventure/images/02-car.pngfor figure drawing. When the image tool supports multiple references, supply the input photograph as the edit target and a relevant bundled illustration as the style reference only. In a new scene, the bundled illustrations are style references only. Never copy their subject, composition, identity or labels into the user's result. Do not redistribute historical research scans. - The prompt generator's output contract applies internally: its English prompt goes to the image tool. The parent skill's user-facing deliverable remains the finished image.
- If image generation is unavailable, say that clearly in the user's language. Do not label an English prompt or a mockup as a generated image. Never silently substitute a different provider or paid API.
Recognize one of three inputs
A — Image. Inspect the photograph. Record the person or subject, face proportions, age, expression, pose, hands, clothing, glasses, recognizable accessories, objects, framing and meaningful setting. Preserve these unless the user explicitly asks to change them. Retain the input aspect ratio by default. A style reference is a different role from the edit target; do not swap them.
B — Scene. Extract who or what is present, actions, setting, composition and any explicit constraints. Keep the scene's content. A scene that is not an adventure keeps its setting: the adventure vocabulary then appears through believable geography, specific props and deep staging, not by moving the scene to an exotic location. If no aspect ratio is supplied, use 16:9 for a scene; follow a stated medium such as a square social post instead when provided.
C — Context. Extract the message, audience, mood and destination from the supplied text or conversation. Choose a concrete, original journey or discovery that stages the message: a route, an obstacle, a destination. Do not invent facts, numbers, quotations or branding. Make the message understandable without text by default. Ask only if materially different interpretations prevent a useful result. Use the requested destination's aspect ratio, otherwise 16:9.
If inputs are combined, infer their roles: for example, an image is the subject and a paragraph supplies the illustration's message. Ask one focused question only when the roles conflict.
Optional adjustments: zero to three
The canonical controls are World, Color, and Gag. Values and defaults live in the tweaks reference. Never weaken the identity of this style by changing its clear storytelling line to a generic filter or another medium.
If the request is clear, apply the explicit values or defaults and generate immediately. Do not require a questionnaire. If the user asks to explore, requests a materially ambiguous adjustment, or a meaningful unresolved choice would change the result, use an AskUserQuestion interaction: the environment's interactive question tool, or the same concise question in chat when no such tool is available.
Offer at most three relevant tweak controls. Ask one focused question at a time, explain its visual effect in plain language, place the recommended/default answer first, and allow a custom answer and discussion. Where tool schemas add free text automatically, do not duplicate it with a fake option. Infer answers already supplied. Do not mistake silence for consent to a material change. If the user simply wants the default image, no question is needed.
Translate questions, explanations and choices into the user's language. Canonical parameter values stay English in prompts and grid labels. Natural-language requests such as "behold stedet, som det er" may be mapped directly to a suitable value (World = Source) without asking again.
Respect a scene's stated lighting and content: a night scene keeps its night palette within the chosen Color, and a request for a serious mood implies Gag = None. Stated content takes precedence over a style default.
Generate, inspect, deliver
- Inspect the input and identify its type and invariants.
- Load the detailed style profile. Resolve any relevant optional adjustments.
- Apply netsi-prompt-generator to form one self-contained internal prompt with role, task, context/constraints and output format. Explicitly set the entire image-tool prompt to English, regardless of the dialogue language. Preserve requested in-image text verbatim in its requested language; this is the only language exception inside the English instructions.
- Include the profile's core traits, their priorities, selected tweak values and the input's exact preservation constraints. If Gag is not None, choose the gag yourself from the subject or setting and describe it concretely in the prompt. Use descriptive traits only. Do not mention artist names, named fictional characters, existing works, studios, signatures or imitation slogans.
- Generate or edit the actual image. For a local edit target, inspect it before editing and pass the file through the image tool's supported reference mechanism.
- Inspect the result: recognize the subject; check face, expression, accessories and hand gesture; check scene content; check the clear storytelling line, expressive acting, specific and believable environment detail, foreground-to-background depth, the requested gag and the four-color palette; check any requested lettering. The style must influence the drawing, not merely add a detailed backdrop to a photograph.
- If a material defect exists, make a focused revision and inspect again. Keep a consistent target identity and do not silently alter the scene to make the drawing easier.
- Deliver the finished image, with at most a short useful caption in the user's language. Keep the internal prompt hidden unless the user explicitly asks for it. Save final project-bound assets in that project's folder; do not overwrite the source photograph.
Never turn a person into an animal or into a known cartoon character, and never draw anthropomorphic animals, sailor outfits, top hats with spats, bills or beaks, or piles of gold coins to swim in. People stay human with their own clothing. Animals that the setting calls for (gulls, goats, pack mules) stay ordinary animals.
Comparison grids
When requested, create one 16:9 image with 4 columns × 3 rows (12 image cells). Use the same subject, identity, pose, objects and crop in every cell. Reserve a legible label strip under each image, inside the overall canvas. Labels contain the exact English parameter names and values, never artist names. Use the schedule in references/tweaks.md: it includes the default and varies World and Color while keeping Gag at Background. A matrix may explore Gag instead if requested, but must state the exact changed values.
Generate the artwork with the image tool. Use supported layout/text composition tools to assemble a precise grid if available; do not use code to imitate the illustration or recolor a photograph as a substitute. A single image-tool call may render the complete labeled grid. Verify 12 cells, order, visible differences, literal labels and a 16:9 canvas (allow one pixel of integer raster rounding) before delivering. Regenerate if lettering or structure is wrong.
Do not claim pixel-identical identity or perfectly isolated experimental control: image generation can vary details. Aim for faithful, visually comparable variations and disclose a material limitation if it remains.
Start with an example
- Attach a photograph: "Apply this style. Keep the face, pose and surroundings recognizable."
- Describe a scene: "Two explorers with a hand-drawn map stand on a cliff ledge above a hidden harbor town. A rope bridge sways, and a gull is stealing their sandwich."
- Supply context: "Illustrate the long road to a product launch for a project kickoff slide. No text in the image."
- Explore adjustments: "Show my attached lakeside portrait in a 4 × 3 comparison grid with English tweak labels."
Bundled generated examples: https://assets.netsi.dk/skills/netsi-style-like-expressive-adventure/images/01-pool.png and https://assets.netsi.dk/skills/netsi-style-like-expressive-adventure/images/02-car.png (photo edits), https://assets.netsi.dk/skills/netsi-style-like-expressive-adventure/images/03-tweak-grid.png (comparison grid), https://assets.netsi.dk/skills/netsi-style-like-expressive-adventure/images/04-cliff-harbor.png (scene) and https://assets.netsi.dk/skills/netsi-style-like-expressive-adventure/images/05-launch-expedition-context.png (context).
Buy me a coffee :-)
Hvis du kan bruge disse skills, kan du støtte arbejdet.
