netsi-style-like-tanaka Version 1.0.0
Kaldes med /netsi-style-like-tanaka
Create photorealistic macro images of miniature dioramas where everyday objects become scenery or furniture. Accepts a reference image, an existing image prompt, or context to illustrate. Use for playful changes of scale, tactile tabletop scenes, or when explicitly invoked.
Ingen Claude Code? Hent SKILL.md og indsæt indholdet som din prompt i en hvilken som helst AI-chat.
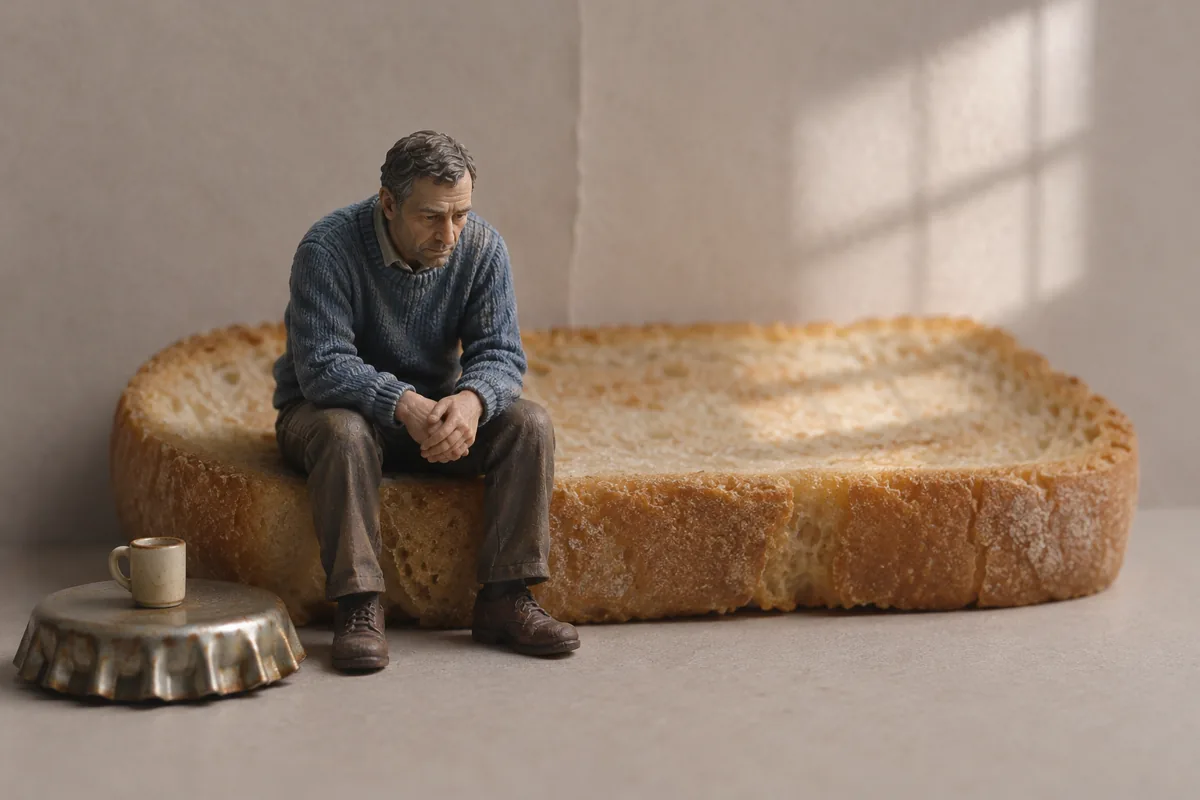
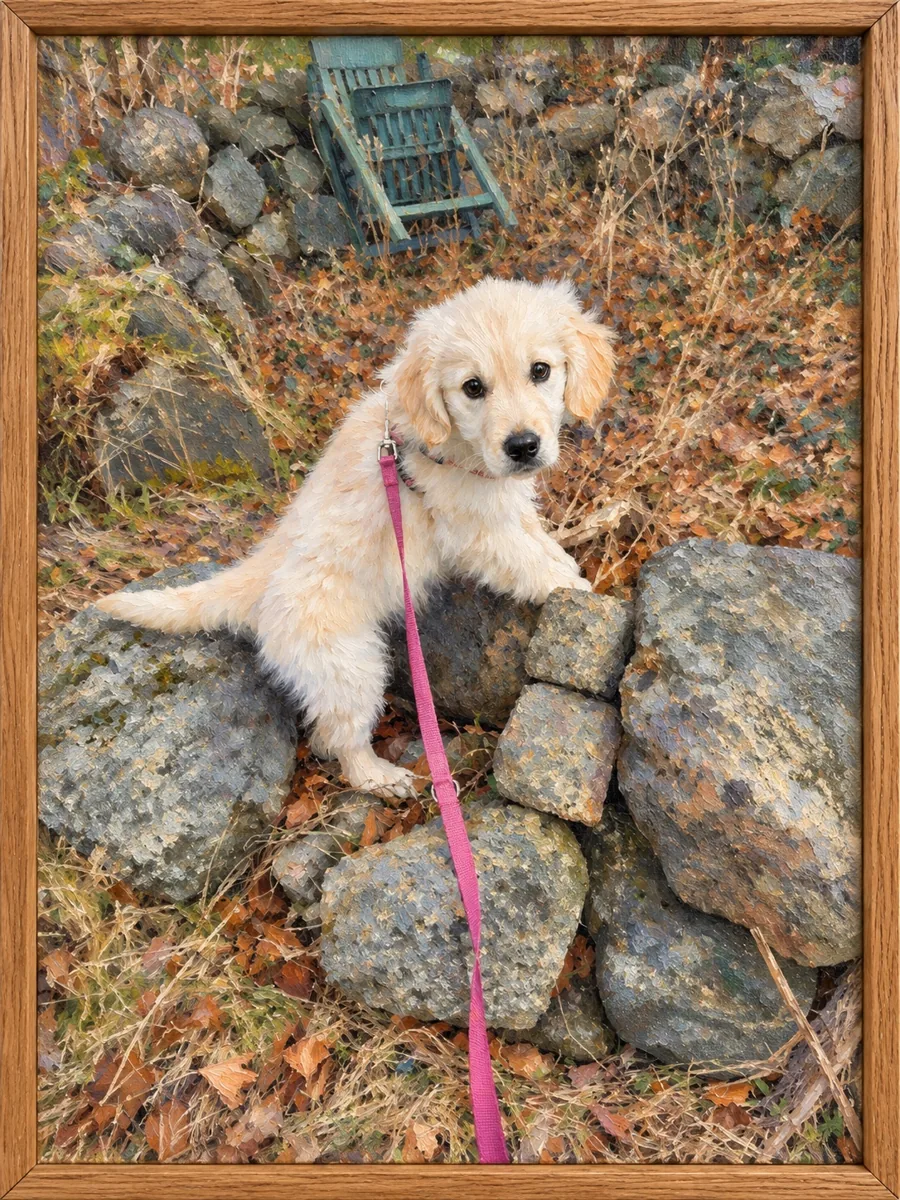
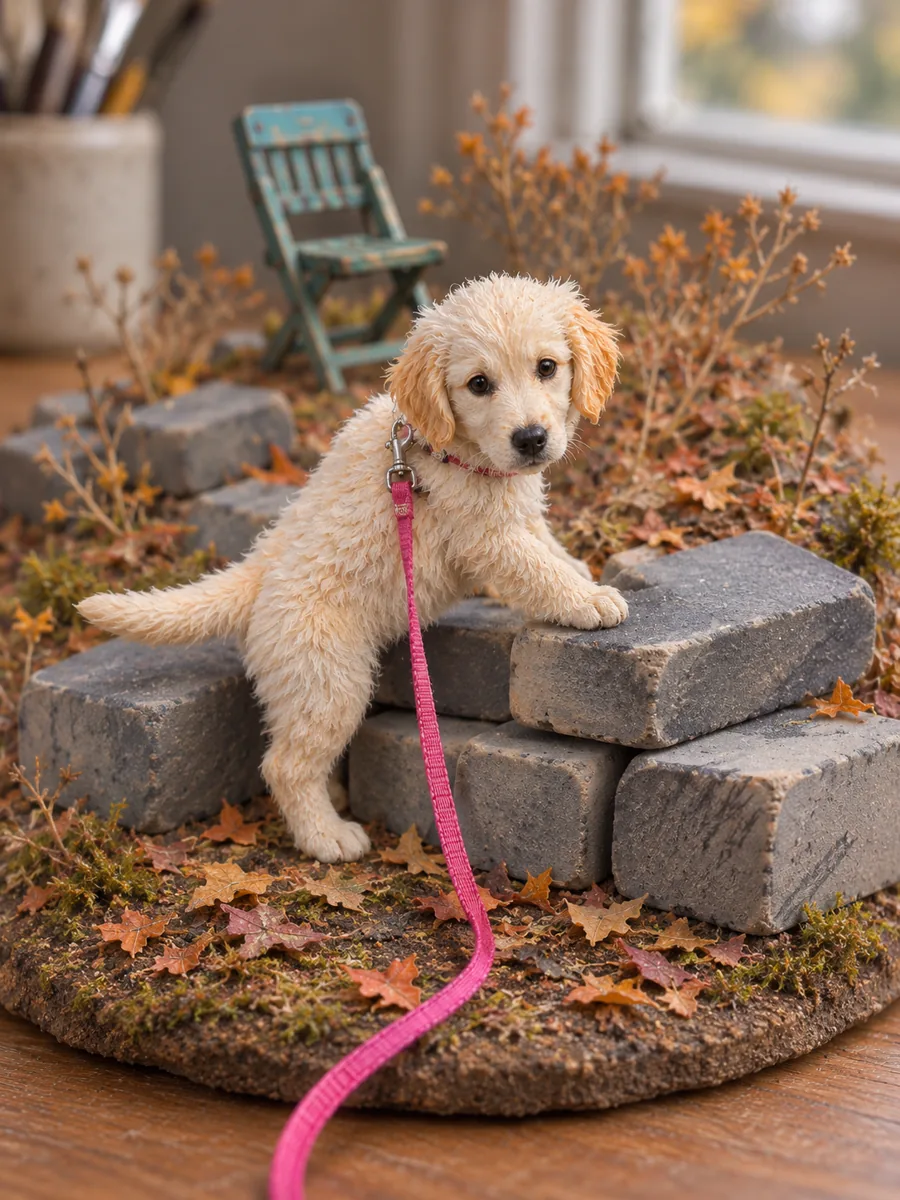
Netsi Style Like Tanaka
Art-direct one handcrafted miniature scene. Choose one ordinary object whose shape makes its new function immediately recognizable. Keep its original material visible: bread crumb can read as upholstery, and the worn edges of erasers can read as boulders. Let the subject interact physically with the object. Use secondary props only where they support the action or mood.
Interpret the input
- Reference image. Inspect the attachment and use it as the edit target. Preserve recognizable appearance, expression, pose and distinctive accessories. Translate the subject into a realistically molded and painted figurine. Adapt the setting into tactile props and keep the original orientation unless instructed otherwise.
- Existing prompt. Preserve the intended subject, action, object roles and explicit constraints. Resolve contradictions and specify how the parts fit together and which details stay sharp.
- Context. Extract the central idea and mood. Choose one concrete moment that reads without text, then pick a common object whose shape supports it. Avoid inventing facts about the people or events involved.
Infer the mode. For combined inputs, apply explicit instructions first, use the image for likeness and visible details, and use the surrounding text for intent. Ask one focused question through AskUserQuestion or the available user-input tool only if an unresolved choice materially changes the subject or scene. Give two or three numbered options with the recommended choice first, in the user's language. With sufficient input, proceed directly.
Compose and render
Write one self-contained English image prompt. Start with the subject, action and object transformation. Add physical placement, realistic material cues and the camera setup. Use nominal HO scale (1:87) for figurines by default and size household props to make the visual analogy work. Prefer an eye-level or low three-quarter macro view, soft directional light and selective focus that keeps both the subject and the central transformation readable. Keep real shadows, believable contact and a restrained background. Use concrete visual traits and omit artist names from the generation prompt.
For a prompt-only request, return the finished English prompt. For an illustration or restyle request, pass the English prompt and any source image to the image tool, then deliver the actual image. Check likeness where applicable, object legibility, contact, and the intended mood. If the image tool is unavailable, report that and provide the English prompt.
Read the two example prompts when calibration would help.
Buy me a coffee :-)
Hvis du kan bruge disse skills, kan du støtte arbejdet.
